Eliminating Compute Bottlenecks in Small Language Models
Optimizing small language models requires sorting inference workloads by token length rather than looping items individually, according to recent technical benchmarks demonstrating significant reductions in wasted compute cycles.
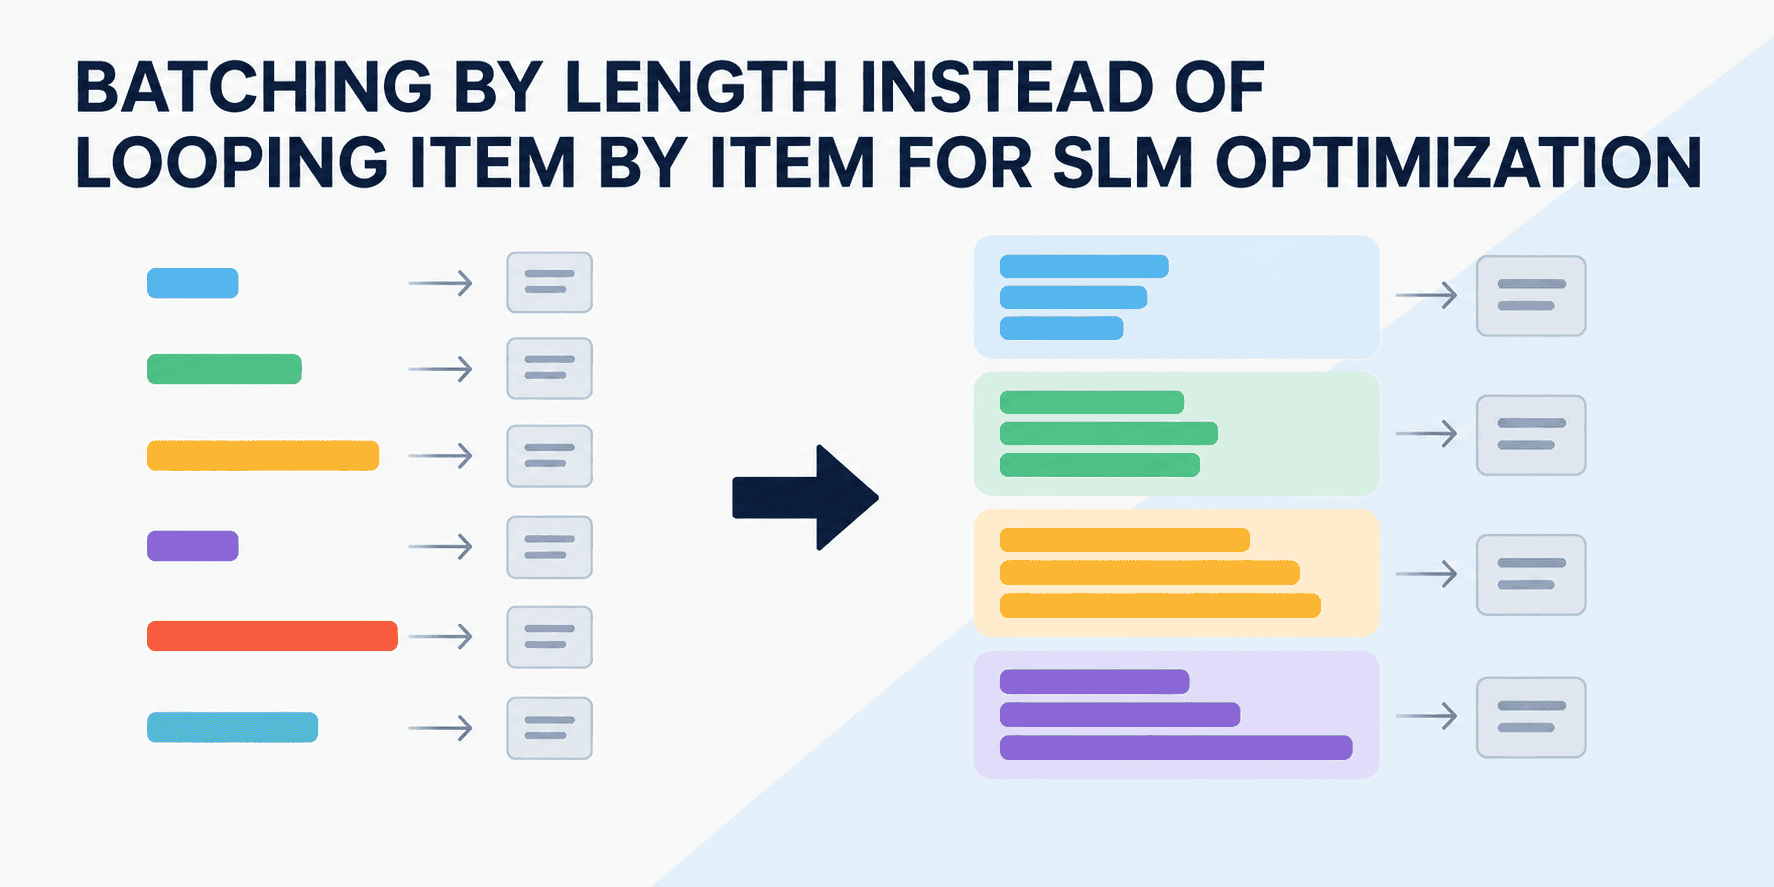
When processing variable-length text data like customer support tickets through models such as Qwen2.5-0.5B-Instruct, traditional single-item pipelines suffer from memory-bandwidth bottlenecks and massive padding inefficiencies. Sorting inputs by length before batching aligns sequence sizes, amortizes weight reads across hardware units, and prevents computational overhead.
The Cost of Single-Item Processing Loops
Processing individual text inputs sequentially is a primary source of inefficiency in machine learning inference pipelines. At a batch size of one, lightweight models like the 0.5-billion-parameter Qwen architecture remain memory-bandwidth bound instead of compute-bound.
The underlying hardware must stream every model weight out of memory to evaluate a single sequence, repeat the process for the next item, and leave arithmetic units largely idle between passes. This performance limitation affects both graphics processing units and standard central processing units, where compact models frequently execute in production environments.
Padding Waste in Long-Tailed Text Distributions
Real-world datasets rarely feature uniform sequence lengths. Customer support logs, chat histories, and document corpuses typically exhibit a long-tailed distribution where median token counts sit well below one hundred, while maximum lengths stretch to several hundred tokens.

Forming uniform batches without sorting forces every sequence in a given group to match the global maximum length through padding tokens.
Empirical benchmarks using datasets with a median length of 94 tokens and a maximum length of 449 tokens reveal that global padding forces systems to process nearly four times the volume of necessary tokens. Computing redundant attention operations over large blocks of padding wastes hardware cycles and degrades overall throughput.
Sorting by Token Length for Efficient Batching
Mitigating padding overhead requires organizing input data by token length prior to batch formation. Grouping similarly sized sequences allows each discrete batch to pad toward its own local maximum rather than a global ceiling.
By implementing sorted batching alongside constrained output scoring—which restricts model generation to predefined classification tokens—developers maximize hardware utilization and increase operational throughput.
This approach eliminates redundant forward passes, reduces memory-bandwidth friction, and ensures that processing pipelines make efficient use of available computing resources.
Worth a look