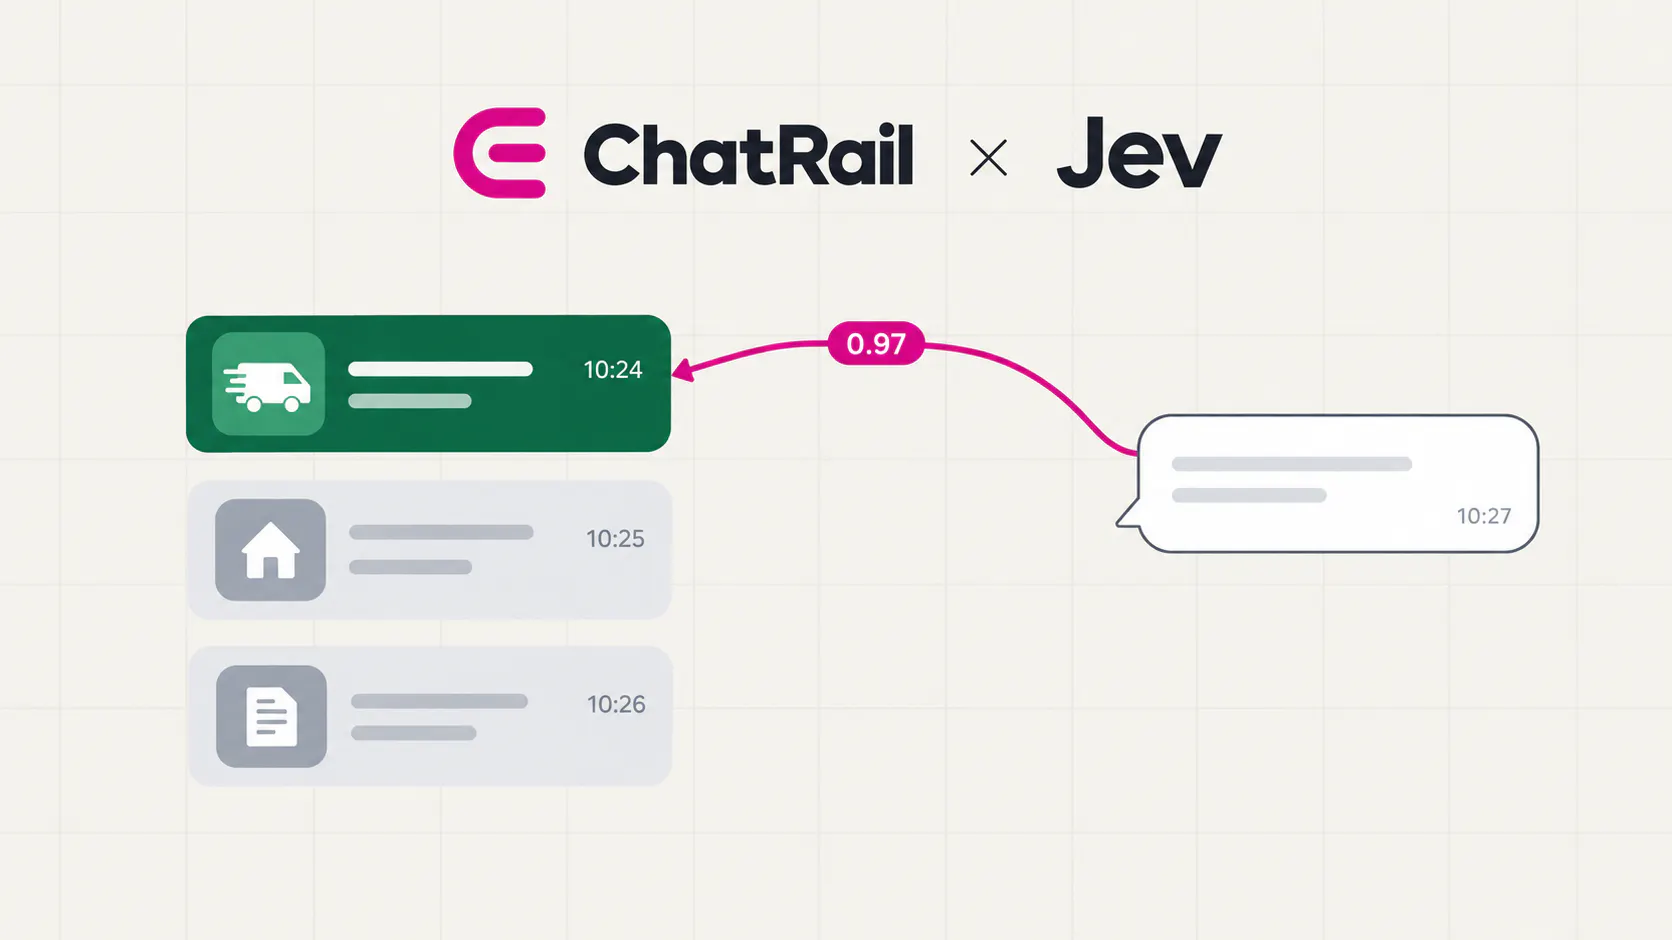
Jev 1.13 Outperforms Gemini and GPT on WhatsApp API Routing Speed
In a technical essay published on HackerNoon, developer ChatRail creator Anika Shah examines the real-world trade-offs of using structured language models for intent matching in messaging applications. The author reports that a newly released, non-generative model called Jev 1.13 matches incoming WhatsApp replies to the correct context faster and at a fraction of the cost of traditional large language models. The piece details benchmark tests run in late September 2026 across OpenRouter, comparing Jev against Gemini 2.5 Flash Lite and GPT-5.6 Luna.
Latency and Cost Comparisons Across OpenRouter
Shah tested Jev 1.13, Gemini 2.5 Flash Lite, and GPT-5.6 Luna using 14 test cases in English, Spanish, and Roman Urdu, alongside a prompt-injection attempt. While all three contenders achieved a 93% accuracy rate in identifying the correct alert, their performance diverged sharply in execution speed and operating expenses. HackerNoon reported that median end-to-end latency reached approximately 350ms for Jev 1.13, compared to 640ms to 1,000ms for Gemini 2.5 Flash Lite and 2.1 to 2.6 seconds for GPT-5.6 Luna. Operating costs tracked through OpenRouter positioned Jev at $0.25 per 10,000 messages, while Gemini 2.5 Flash Lite cost $0.41 and GPT-5.6 Luna ranged from $1.20 to $1.30 for the same volume. Because intent matching occurs before a reply can be generated, the author argues that multi-second latencies noticeably degrade the messaging experience.
Simulation Results in Real-World API Workflows
Moving beyond static benchmarks, Shah deployed a simulation script through the actual ChatRail API and worker architecture to evaluate live performance. The test involved 12 contacts receiving multiple spaced-out alerts followed by ambiguous replies sent without the platform’s native reply buttons. While traditional rule-based matching correctly linked only 3 out of 12 messages—succeeding exclusively when the newest alert happened to be correct—Jev 1.13 achieved a 12 out of 12 success rate. Every successful pick registered a confidence score of 0.97 or higher, with the total cost for all 12 simulation calls totaling $0.00027. The author notes that Jev’s ability to return a definitive “none of these” output proved essential for handling out-of-context replies accurately.
Keep reading