NVIDIA Blackwell Ultra Delivers 50x Performance Boost for Agentic AI
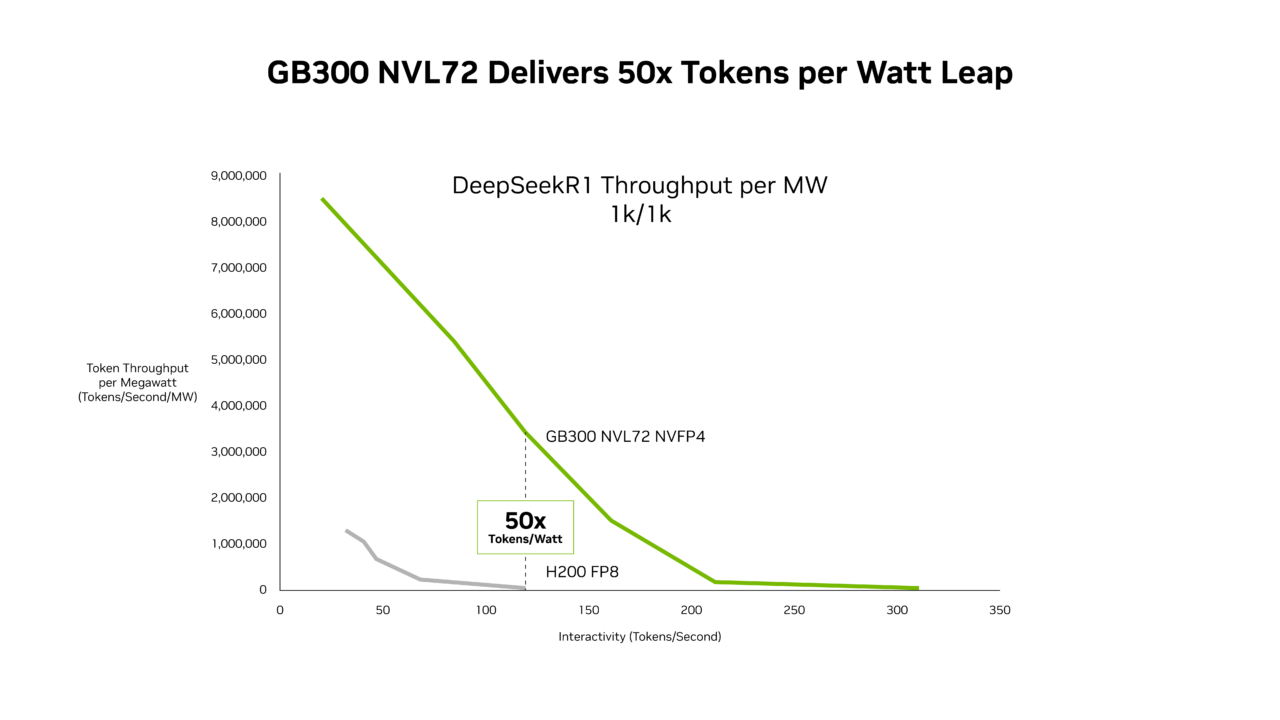
NVIDIA’s latest Blackwell Ultra platform is poised to dramatically accelerate the development and deployment of AI agents and coding assistants, offering up to 50 times higher throughput per megawatt and a 35 times reduction in cost per token compared to the previous Hopper generation. This leap in performance is driven by innovations across NVIDIA’s chip design, system architecture, and software stack.
The Rise of Agentic AI and Demand for Performance
The demand for AI agents and coding assistants is surging. According to OpenRouter’s State of Inference report, AI queries related to software programming have increased from 11% to approximately 50% in the past year. These applications require both low latency for real-time responsiveness and the ability to process long contexts – essential for reasoning across entire codebases.
Blackwell Ultra: A Breakthrough in Performance and Efficiency
NVIDIA’s GB300 NVL72 systems, powered by the Blackwell Ultra platform, deliver significant improvements in both performance and cost-efficiency. SemiAnalysis InferenceX data demonstrates up to a 50x higher throughput per megawatt and a 35x lower cost per token compared to the NVIDIA Hopper platform.
Signal65 analysis indicates that the GB200 NVL72, utilizing extreme hardware and software co-design, achieves more than 10x more tokens per watt, reducing the cost per token to one-tenth compared to the Hopper platform.
Software Optimizations Fuel Performance Gains
Continuous optimizations from NVIDIA teams working on TensorRT-LLM, Dynamo, Mooncake, and SGLang are significantly boosting Blackwell NVL72 throughput for mixture-of-experts (MoE) inference across all latency targets. Improvements to the NVIDIA TensorRT-LLM library alone have increased low-latency workload performance by up to 5x on GB200 compared to just four months prior.
Key technical improvements include high-performance GPU kernels optimized for efficiency and low latency, maximizing Blackwell’s computational power. NVIDIA NVLink Symmetric Memory enables efficient communication through direct memory access between GPUs, and the Programmatic Dependent Launch feature minimizes idle time by starting the setup phase of the next kernel before the previous one completes.
Cost-Effectiveness for Long-Context Workloads
While both GB200 NVL72 and GB300 NVL72 offer ultra-low latency performance, the GB300 NVL72 particularly excels in long-context environments. For workloads processing 128,000 tokens in and 8,000 tokens out – such as AI coding assistants reasoning across a codebase – the GB300 NVL72 reduces the cost per token by up to 1.5 times compared to the GB200 NVL72.
Blackwell Ultra features 1.5 times the NVFP4 computation performance and 2 times the attention processing speed, enabling agents to efficiently understand entire codebases.
Industry Adoption and Future Outlook
Major cloud service providers, including Microsoft, CoreWeave, and Oracle Cloud Infrastructure, are already deploying GB300 NVL72 systems in production environments. This adoption is driven by the potential to reduce token costs and enable new applications capable of real-time inference on large codebases.
Looking ahead, NVIDIA anticipates further performance improvements and cost reductions as Blackwell systems are deployed at scale. The upcoming NVIDIA Rubin platform, integrating six new chips into a single AI supercomputer, promises another significant leap in performance, with throughput per megawatt potentially improving by up to 10x compared to Blackwell and the cost per million tokens reduced to one-tenth.
Related reading