Antibacterial drug development is declining as global resistance rates climb, forcing a reliance on artificial intelligence to predict which treatments will work for specific infections.
In October 2025, the World Health Organization reported that the pipeline for new antibacterial agents had dropped from 97 to 90 over the previous two years, with only five candidates targeting pathogens classified as “critical.”
This scarcity of new drugs makes rapid, accurate diagnostics essential for patient survival. While AI models show promise in analyzing microbial genomes to determine drug susceptibility, their effectiveness remains hindered by poor-quality training data, according to reviews from a EUCAST subcommittee and a joint study by the Align Foundation and Google DeepMind.
AI models currently struggle because they rely on antimicrobial susceptibility testing (AST) results that often lack historical context. As the Clinical and Laboratory Standards Institute periodically revises its clinical breakpoints—such as the 2010 adjustment for carbapenem resistance in Enterobacteriaceae—older data can become misleading.
“When a label loses that context, it quietly corrupts training data,” researchers noted. Furthermore, public databases like the National Institutes of Health’s GenBank contain significant errors; a 2020 analysis identified more than 2 million contaminated entries where DNA from multiple organisms was mislabeled as a single pathogen.
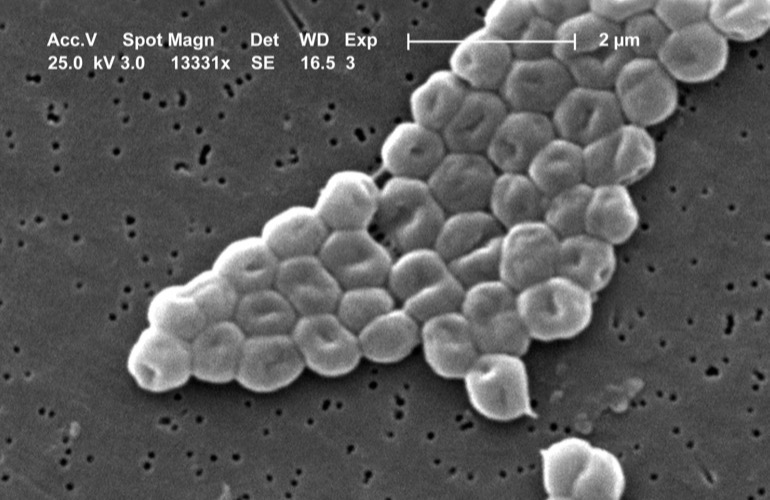
Current models often rely on a binary presence-or-absence check for resistance genes, which fails to account for biological complexity. In species such as Acinetobacter baumannii, resistance is frequently driven by mobile genetic elements like ISAba1 that activate existing chromosomal genes rather than by the presence of the gene alone.
Heteroresistance, where a small subpopulation of resistant cells hides within a susceptible culture, represents another blind spot. Standard testing often misses these cells, leading to inaccurate training data that can cause an AI to misidentify a dangerous strain as susceptible.
A 2024 study comparing machine-learning models against the rule-based tool ResFinder showed that the models performed differently. When tested against strains less closely related to the training strains, ResFinder outperformed machine-learning models on 44% to 50% of datasets.
To build reliable tools, the industry must move toward using authenticated strains where the genome and the minimum inhibitory concentration (MIC) are generated from the same physical isolate. Researchers suggest utilizing standardized methods, such as ISO 20776-1 broth microdilution, to ensure data consistency.
Moving forward, the development of community-governed test sets that include borderline and discordant cases will be necessary to validate AI performance. This approach would allow developers to monitor how well models recognize emerging resistance patterns.
Why are susceptible isolates missing from public databases?
Susceptible isolates are rarely uploaded because they are often viewed as unremarkable. However, AI models require these negative results to learn how to distinguish susceptible genomes from resistant ones.
How does temporal data affect AI training?
Resistance evolves over time, and training on historic strains helps models understand how pathogens progressively acquire resistance genes. By using collections of both recent and older isolates, developers can teach algorithms to identify novel variants as they emerge.
Related reading