Amazon S3: Two Decades of Shaping Cloud Storage
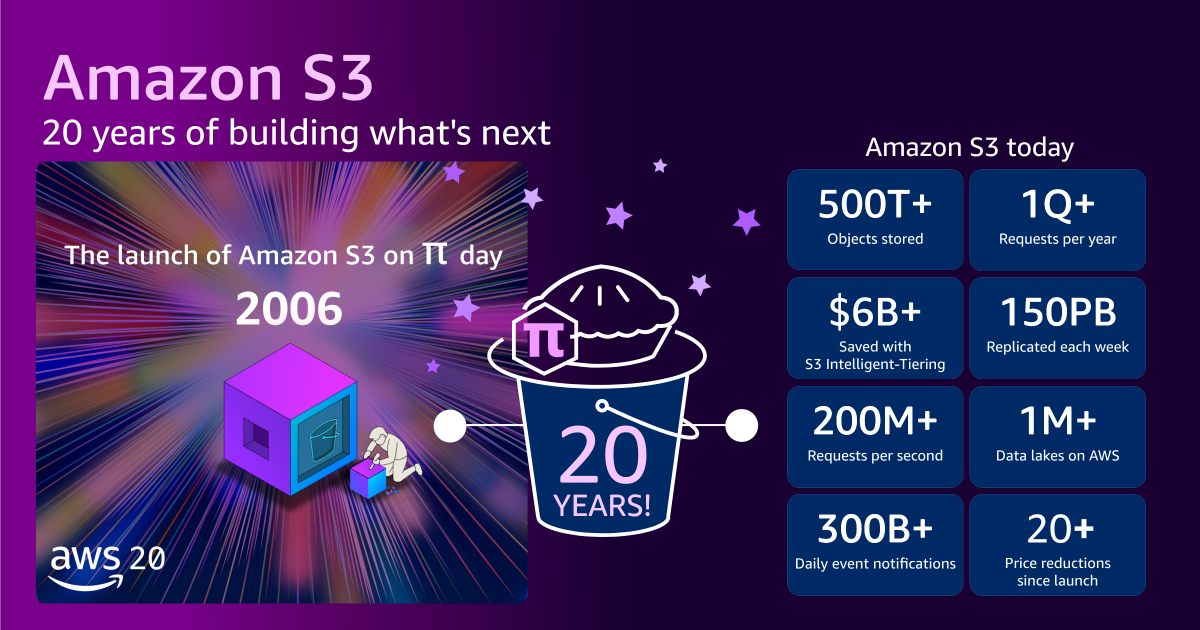
Twenty years ago, on March 14, 2006, Amazon launched Simple Storage Service (Amazon S3), a service that has fundamentally reshaped the landscape of cloud computing. Initially announced with a single paragraph on the AWS What’s New page, S3 offered a simple web services interface for storing and retrieving data, aiming to make web-scale computing more accessible to developers.
The Genesis of S3: Building Blocks for the Internet
Amazon S3 was conceived as a foundational service – “storage for the Internet.” Its initial design focused on two core operations: Place (to store an object) and GET (to retrieve it). The key innovation wasn’t just the functionality, but the philosophy behind it: providing basic building blocks that handled complex infrastructure tasks, allowing developers to concentrate on building applications. As Jeff Barr noted in the original announcement, the launch was understated, preceding a developer event with minimal fanfare.
Core Principles: Security, Durability, and Scalability
From its inception, S3 was guided by five core principles that remain central to its operation today:
- Security: Protecting data by default.
- Durability: Designed for 99.999999999% (11 nines) data durability, ensuring data is not lost.
- Availability: Engineered for high availability, anticipating and handling failures.
- Performance: Optimized to maintain speed and efficiency regardless of data volume.
- Elasticity: Automatically scaling storage capacity up or down as needed, without manual intervention.
S3 Today: Scale Beyond Imagination
Over the past two decades, S3 has grown to an astonishing scale. At launch, it offered approximately one petabyte of storage across 400 storage nodes in 15 racks within three data centers, with a total bandwidth of 15 Gbps. It was designed to store billions of objects, each up to 5 GB in size, at a price of 15 cents per gigabyte.
Today, Amazon S3 stores more than 500 trillion objects and processes over 200 million requests per second globally. It spans hundreds of exabytes of data across 123 Availability Zones in 39 AWS Regions, serving millions of customers. The maximum object size has increased tenfold, to 50 TB. The cost has similarly dramatically decreased to slightly over 2 cents per gigabyte – an approximately 85% reduction since 2006.
Customers have collectively saved over $6 billion in storage costs by utilizing Amazon S3 Intelligent-Tiering compared to Amazon S3 Standard.
Industry Impact and API Compatibility
The S3 API has become a standard in the storage industry, with numerous vendors offering S3-compatible storage solutions. This widespread adoption means that skills and tools developed for S3 are often transferable to other storage systems, fostering greater accessibility within the broader storage landscape. Notably, code written for S3 in 2006 remains compatible today, demonstrating a commitment to backward compatibility even through significant infrastructure evolution.
Engineering Innovations
S3’s scale is underpinned by continuous engineering innovation. A system of microservices continuously inspects every byte of data, automatically triggering repair systems when degradation is detected. The service is designed to be lossless, with replication and re-replication strategies sized to achieve its 11 nines durability goal.
Amazon employs formal methods and automated reasoning to verify the correctness of S3’s code, ensuring consistency in operations like cross-Region replication and access policies. Over the past eight years, performance-critical code has been progressively rewritten in Rust, enhancing performance and eliminating potential bugs through Rust’s type system and memory safety features.
S3’s design embraces the principle that “scale is to your advantage,” meaning that increased scale improves reliability and performance for all users.
The Future of S3: A Universal Foundation for Data and AI
Amazon’s vision for S3 extends beyond simple storage to become a universal foundation for all data and AI workloads. The goal is to enable users to store data once in S3 and access it directly for various applications, eliminating the need for data duplication and reducing complexity and costs.
Recent launches include:
- S3 Tables: Fully managed Apache Iceberg tables with automated maintenance for optimized query efficiency and reduced storage costs.
- S3 Vectors: Native vector storage for semantic search and Retrieval-Augmented Generation (RAG), supporting up to 2 billion vectors per index with sub-100ms query latency. Over 250,000 indices were created, ingesting over 40 billion vectors and processing over 1 billion queries between July and December 2025.
- S3 Metadata: Centralized metadata for instant data discovery, streamlining data lake cataloging and accelerating time-to-insight.
These capabilities operate within S3’s cost structure, making traditionally expensive database or specialized systems economically feasible at scale.
From its humble beginnings of 1 petabyte to hundreds of exabytes, and from 15 cents to 2 cents per gigabyte, Amazon S3 has evolved from basic object storage to a cornerstone of modern data analytics and artificial intelligence. The core principles of security, durability, availability, performance, and elasticity remain unchanged, and the commitment to backward compatibility ensures that your code from 2006 continues to work today.
Worth a look