The Promptware Kill Chain: A New Era of AI Security Threats
Attacks targeting modern generative artificial intelligence (AI) large language models (LLMs) represent a growing and sophisticated threat. Current discussions often center on “prompt injection,” techniques to embed malicious instructions within inputs to LLMs. Yet, this framing overlooks a more complex reality: attacks on LLM-based systems have evolved into a distinct class of malware execution mechanisms, termed “promptware.” A new framework, the “promptware kill chain,” provides policymakers and security practitioners with a structured vocabulary and approach to address this escalating AI threat landscape.
Understanding the Promptware Kill Chain
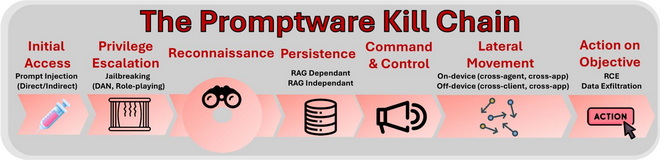
The promptware kill chain outlines a seven-step process mirroring traditional malware campaigns. It begins with Initial Access, where malicious payloads enter the AI system. This can occur directly through user-supplied prompts or, more insidiously, through indirect prompt injection. Indirect injection embeds malicious instructions in content the LLM retrieves, such as web pages, emails, or documents. As LLMs become multimodal – processing various input types beyond text – this attack vector expands to include images and audio files.
Unlike traditional computing systems that separate code from data, LLMs process all input as a single sequence of tokens. This architectural characteristic means malicious instructions embedded in seemingly harmless content are processed with the same authority as system commands.
The Stages of a Promptware Attack
- Privilege Escalation (Jailbreaking): Attackers circumvent safety training and policy guardrails, often through techniques resembling social engineering or adversarial suffixes, to unlock the full capabilities of the model.
- Reconnaissance: The attack manipulates the LLM to reveal information about its assets, connected services, and capabilities, enabling autonomous advancement without detection. This occurs after initial access and jailbreaking.
- Persistence: The promptware embeds itself into the long-term memory of an AI agent or poisons the databases it relies on, ensuring the attack continues beyond a single interaction.
- Command-and-Control (C2): Establishing C2 allows the promptware to evolve into a controllable trojan, with its behavior modified by the attacker.
- Lateral Movement: The attack spreads to other users, devices, or systems, exploiting the interconnectedness of AI agents with emails, calendars, and enterprise platforms.
- Actions on Objective: The final stage involves achieving malicious outcomes, such as data exfiltration, financial fraud, or even physical world impact. This can include manipulating agents to execute arbitrary code, granting attackers total system control.
Real-World Examples of the Promptware Kill Chain
The promptware kill chain has already been demonstrated in practice. Research highlighted in Multimodal Prompt Injection Attacks: Risks and Defenses for Modern LLMs, showed attackers achieving initial access by embedding a malicious prompt in a Google Calendar invitation title. This prompt leveraged a technique known as delayed tool invocation to execute injected instructions, persisting in the user’s workspace and ultimately livestreaming video of the user.
Another example, detailed in the same research, involved injecting a prompt into an email. This prompt used role-playing to compel the LLM to follow the attacker’s instructions, replicating itself and exfiltrating sensitive user data, leading to further infection through email replies.
Defending Against Promptware
Prompt injection is only the first step in a sophisticated attack. Effective defense requires a comprehensive strategy that assumes initial access will occur and focuses on breaking the chain at subsequent stages. This includes limiting privilege escalation, constraining reconnaissance, preventing persistence, disrupting C2, and restricting agent actions. Shifting from reactive patching to systematic risk management is crucial for securing these critical systems.
Further information on LLM security risks can be found in the OWASP Top 10 for Large Language Model Applications and resources from AWS and Cloudflare.
Related reading